The email to worry about is the one that never arrived.
Backup reports, scheduled jobs, system alerts: dozens of emails a day that should arrive. Then there are the sites that must answer, and the backups that write to nobody. Mail Monitor watches all three: the email, the service, the job, and tells you when one is missing.
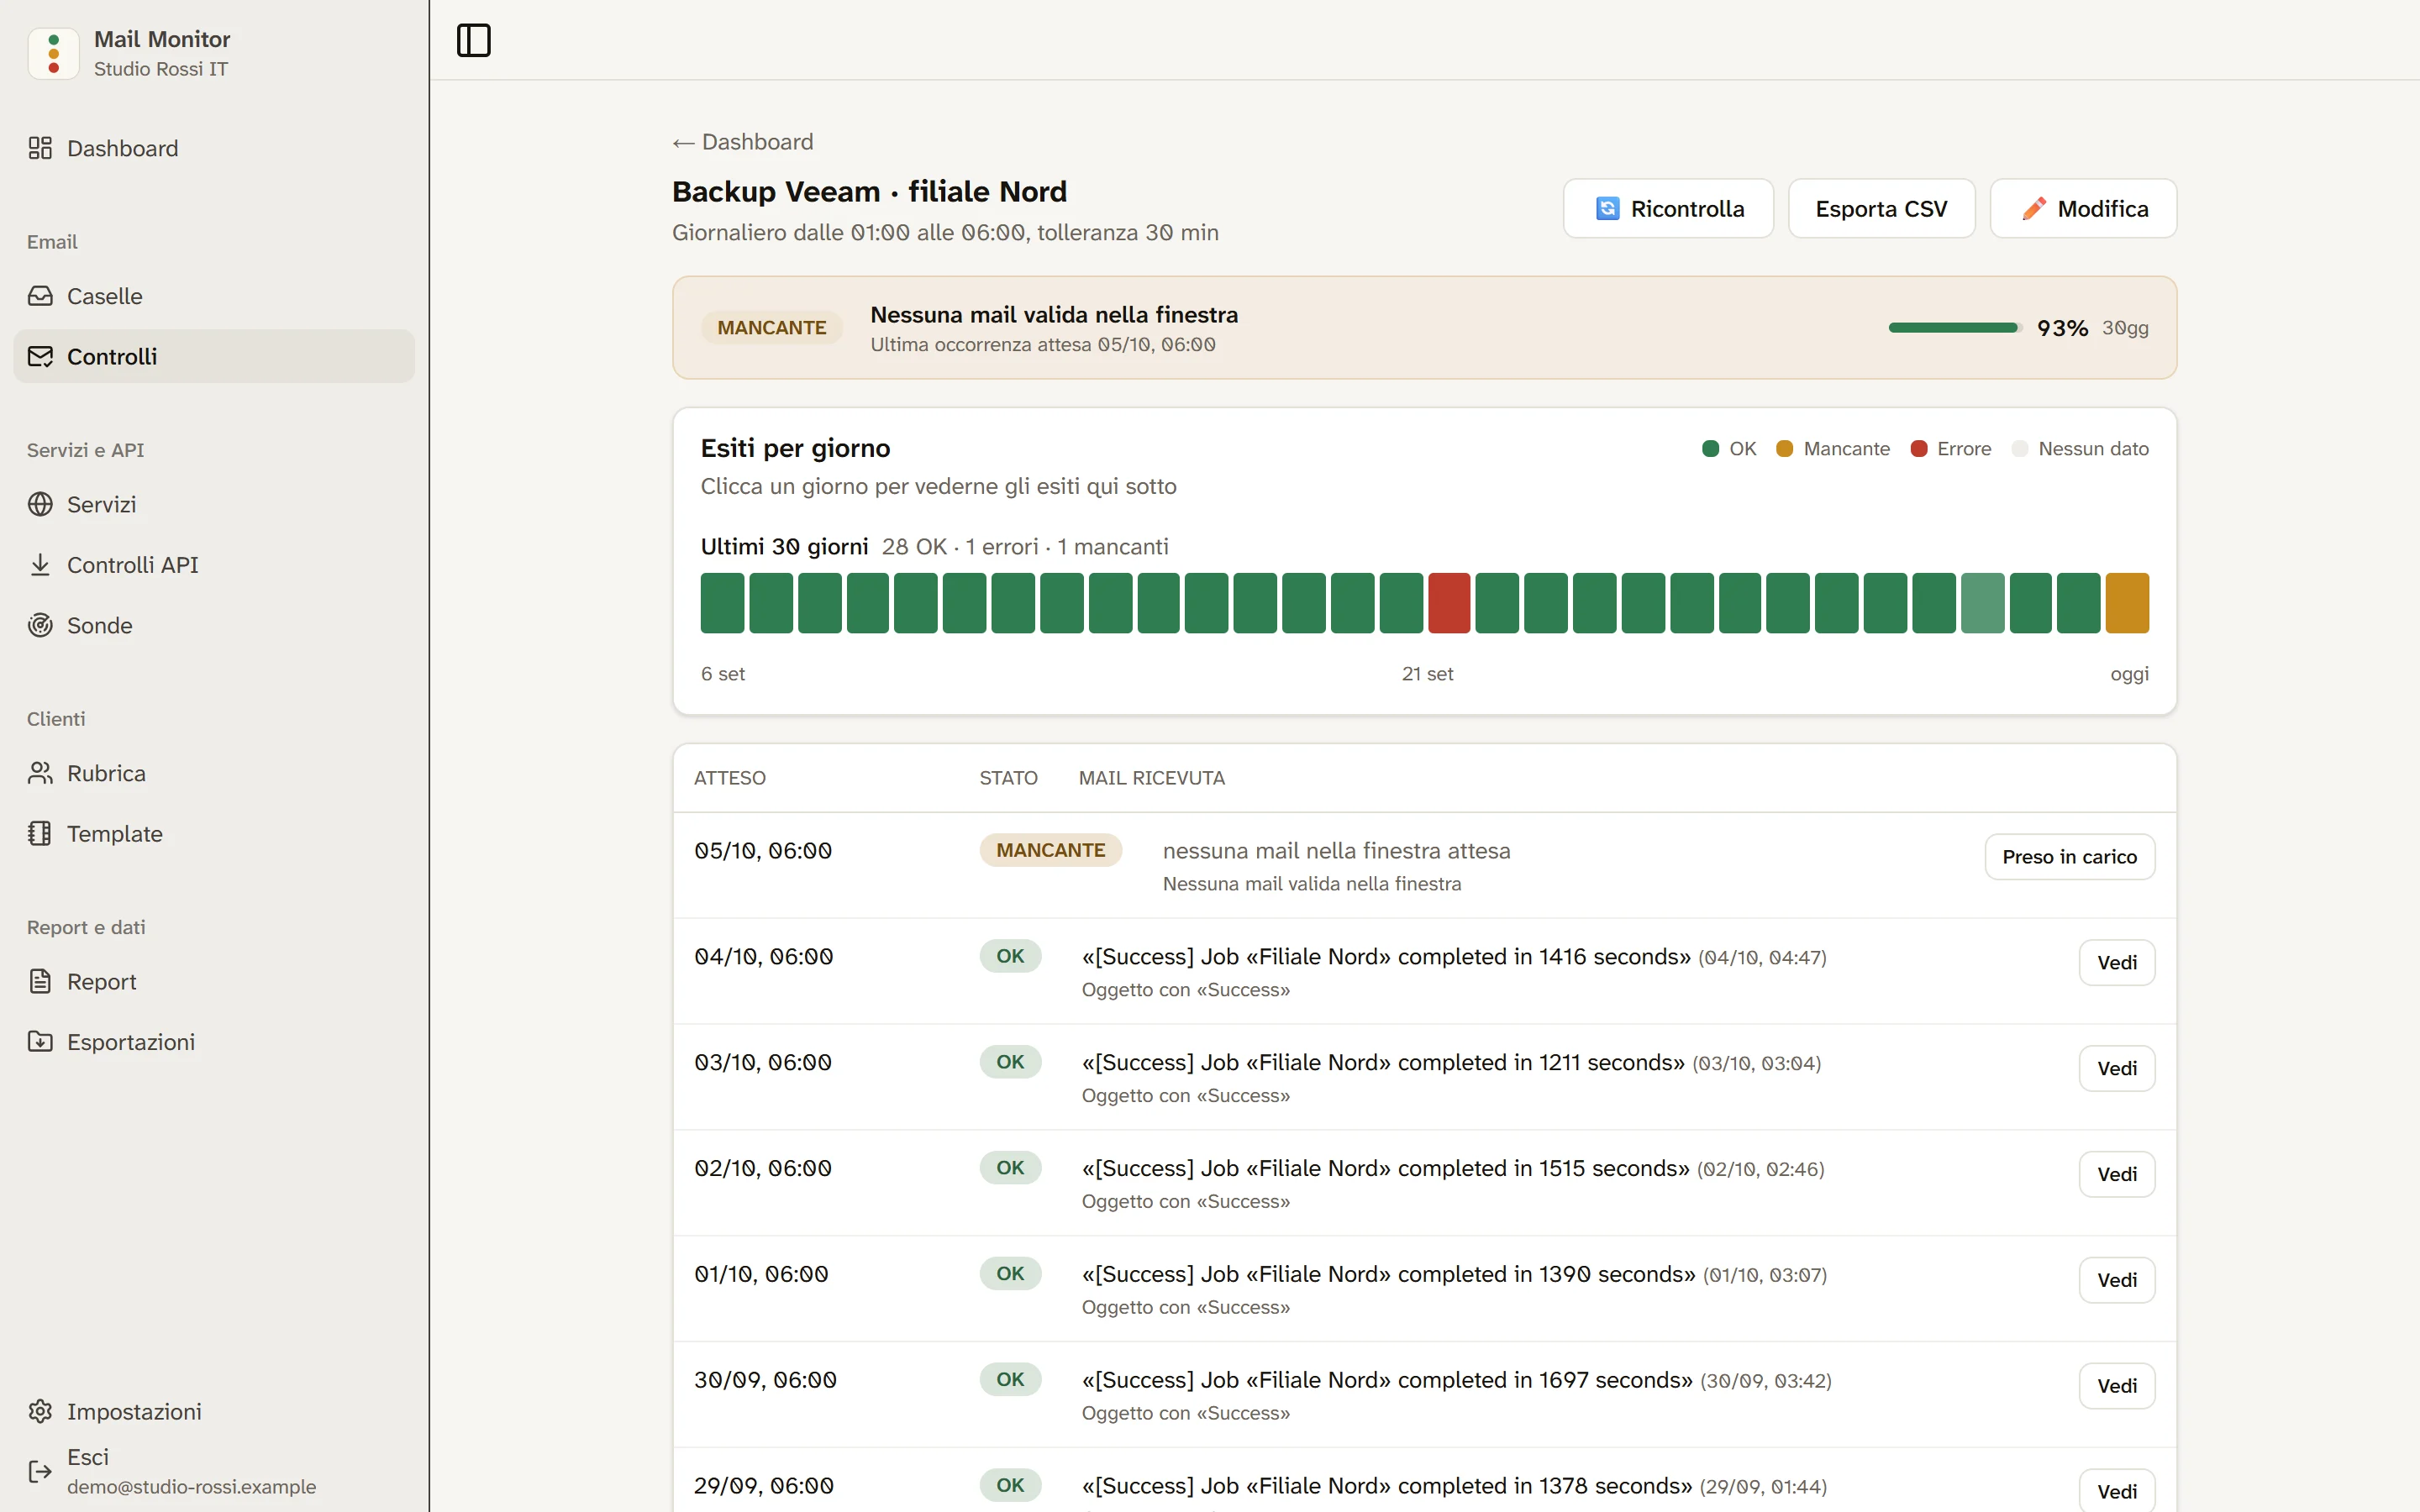
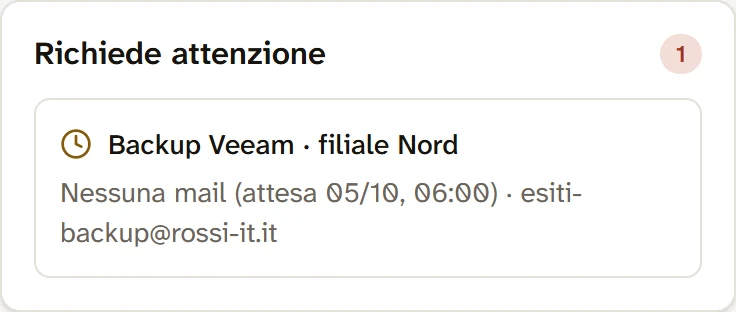
No result email by 06:00. The last one arrived yesterday at 05:41.
The highlighted row is the backup nobody would notice.
02:00The backup starts. Or maybe not.
Dozens of backup status emails. Nobody reads them all.
Backups, scheduled jobs, alerts, automated reports: plenty of systems write to you when they finish. The problem is not the email that says “Failed”: sooner or later, someone notices that one.
The problem is the email that never arrives at all. The job never started, the agent died, the server is off. No error, no red line: just silence.
“No news is not good news. It is the first thing you should be checking.”
Emails, services, cron jobs and on-site servers: four ways to find out.
Not every system speaks the same way: some write to you, some answer if you ask, and some say nothing to anyone. Mail Monitor treats them all as the same object: a check with an outcome.
EmailIMAP
ServicesHTTP
API checksheartbeat
On-site probeWindows
Email
IMAP
read-only
The ones that write to you. Connect the mailbox over IMAP, always read-only. Then describe the email you expect and the window it must arrive in: sender, must contain “Success”, must not contain “Failed”. You can build the rules from an email you have already received.
The ones you can ask. HTTP checks using GET, HEAD or POST with a body, an expected status and filters on body and headers; or plain TCP on a port: RDP 3389, SQL 1433, SSH 22, SMTP 25. One service groups several addresses: if they go down together, you get a single alert. You choose the pace, down to every minute. On the Premium plan, a response-time threshold too.
API checks
Heartbeat
Premium
The ones that talk to nobody. Here the backup calls a URL of ours when it finishes: if the call does not arrive within the expected window, the check turns MISSING. A dead man’s switch for restic and borg scripts in cron, NAS boxes, nightly pg_dumps. The URL is healthchecks.io-compatible: /start times the job, /fail or a non-zero exit code reports the failure. Ready-made snippets for curl, PowerShell, borgmatic, Duplicati and Proxmox Backup Server.
On-site probe
Windows
Linux
Docker
Premium
The ones you cannot see from outside. A small service you install on your network, on a server or a NAS, linked to your account with a token. From there it checks internal servers (HTTP, TCP, ping), backup files (present, recent, big enough), services and processes, and, if you enable them on the machine itself, scripts with an expected result. If the connection drops it keeps checking and delivers everything when it is back. It updates itself, no reboots.
06:00The wait is over.
Four steps. Then it takes over.
For every check you say what you expect and by when. When time is up, every wait becomes a result: arrived, wrong or missing.
01
Connect the source
The IMAP mailbox that receives the emails to watch, the address of the service to probe, or the URL your job will call when it finishes. Mailboxes are always opened read-only: nothing is marked, moved or deleted.
curl -fsS https://ping.ihmonitor.com/7f3a…c21 # when the backup ends
02
Describe what you expect
“An email like this, every day by 06:00.” “This address, every minute.” Every N hours, daily, weekly or monthly, with a cut-off time and a tolerance, because a minute late is not a failure. For calendars that do not fit, the Premium plan takes a cron expression.
“An email like this, every day by 06:00.”
arrived 05:12
00:0006:0012:0018:0024:00
window 04:00–06:00tolerance
every dayMon–Frievery 4 hourscron 0 5 * * 1-5
03
Set the rules
Required and forbidden words in subject and body, expected HTTP status, conditions on the response content. On the Premium plan, thresholds on numbers as well: response time, job duration, a figure written in the email. All testable right away: email rules against the last 50 messages already fetched, services with “Test now” even before you save.
From: veeam@nas-north · 05:12
[Success] Job “North branch” completed in 1438 seconds
must contain Success
must not contain Failed, Warning
“completed in # seconds” below 3600Premium
Tested right away on the mailbox’s last 50 emails: 50 recognised, 49 OK, 1 ERROR.
04
Watch the traffic light
Every expectation becomes an outcome: OK, ERROR or MISSING. Instant alert, daily digest, or dashboard only. Acknowledge what you are already handling, pause what is down for maintenance. And if you want, the alert also reaches your end customer, from your SMTP server and with your logo. At the end of the month, on the Premium plan, the availability report too.
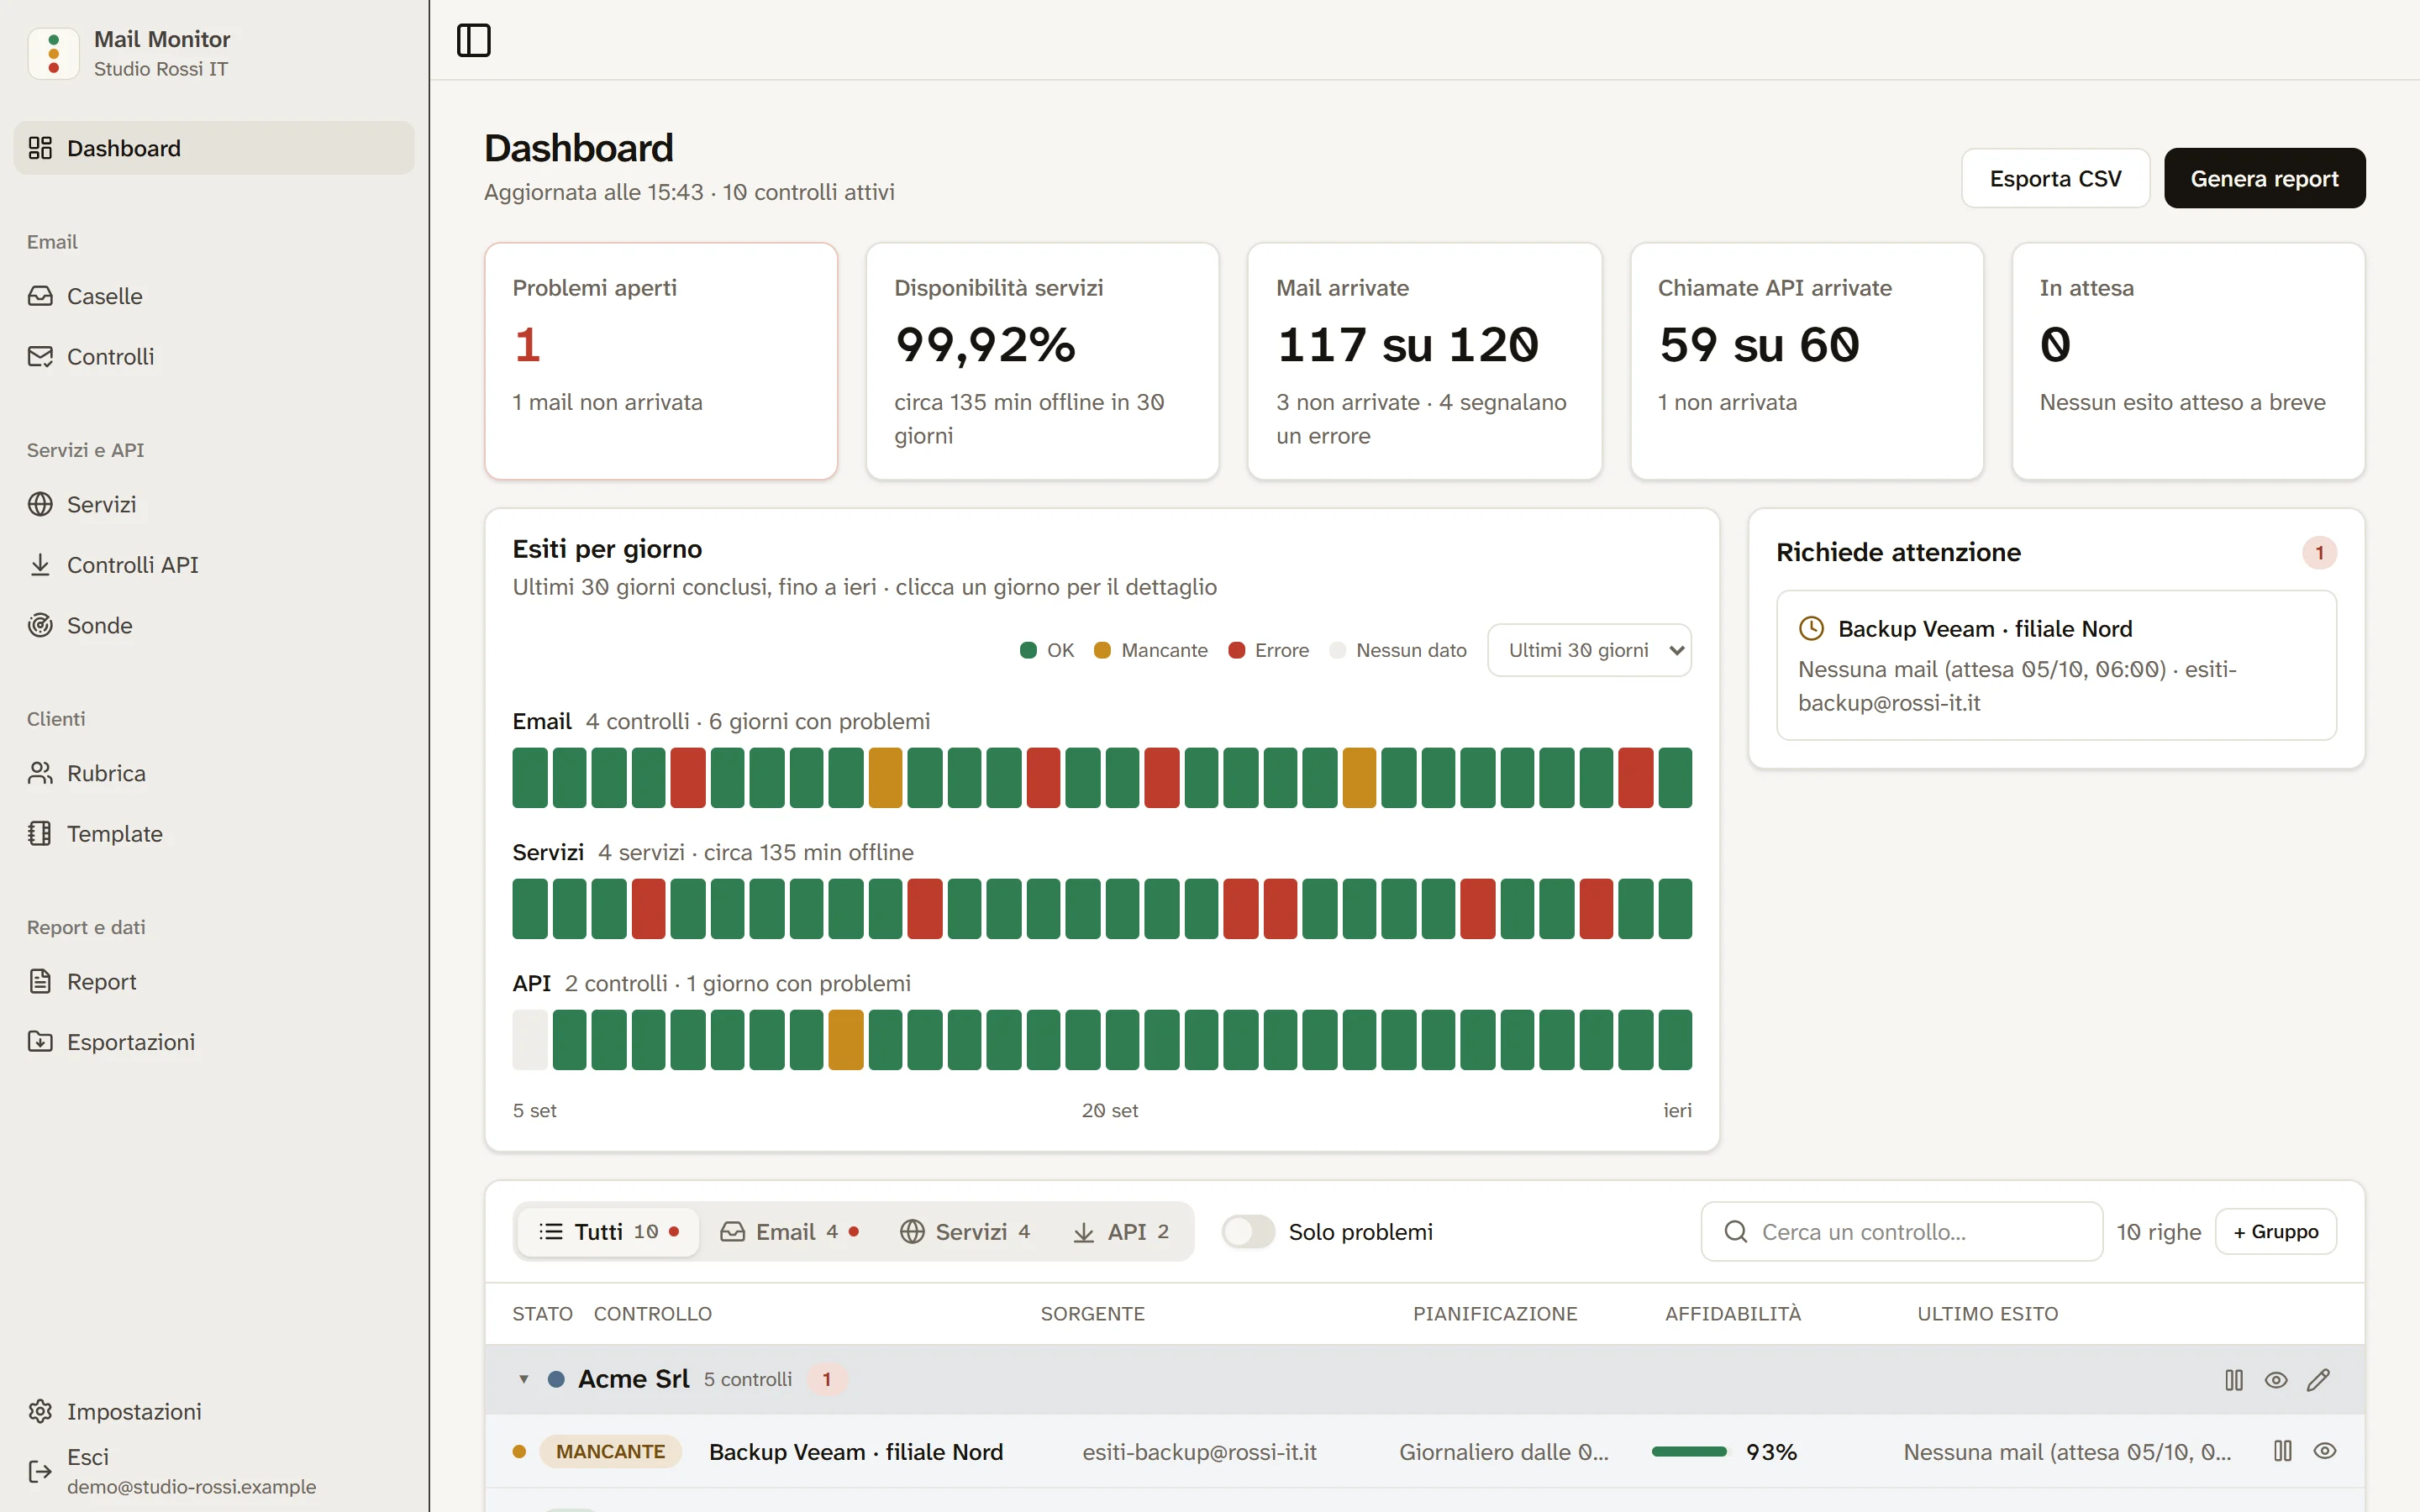
Outcomes per day · Email
to you · right away
North branch backup: MISSING
to your customer · from your SMTP
We are checking your backup
Acknowledge what you are already handling; pause what is down for maintenance.
06:01Someone knows.
Here, colour means something.
Everything else is black and white. Green, red and amber appear only where they carry information: the state of a check. No decorative colour, no noise. One glance tells you what to look at.
Hi Acme, at 09:39 the ERP came back online after a 5-minute outage. No action needed on your side.
Telegram · on call · 06:01
Veeam backup North branch: MISSING
OK
The email arrived within the expected window, the service answered as it should, the job checked in. Everything went as planned.
ERROR
The signal arrived, but it is the wrong one: error words in the email, an unexpected HTTP status, a closed port, a job reporting its own failure. Something ran, and something went wrong.
MISSING
The window closed and nothing arrived. This is the case nobody sees today, and the reason this tool exists.
PENDING
The window is still open. Computed on the fly, never a false alarm ahead of time: we wait until the tolerance runs out.
Detects what never arrives
The heart of the tool: if nothing shows up within the expected window, the state turns MISSING and the alert goes out.
One alert, only when it counts
A consecutive-error threshold before anything fires, a single email per service even when several addresses go down, and “acknowledged”, with a written note, to silence what you are already handling.
08:30The overview, with coffee.
Little to configure, nothing to forget.
The numbers that matter at the top: open problems, service availability, emails received (“25 of 29”), API calls received. Below, day-by-day outcomes for each source: click a day to see what went down, when and why. Alongside, what needs attention. A tab per source, “problems only”, search; on a phone each row becomes a card.
Service availability
99.92%
Emails received
117 of 120
And also
Content rules
Sender, required and forbidden words as chips, including on text extracted from HTML emails. Build them from an email you have already received, and every outcome states its reason. The same conditions apply to a service response.
Thresholds on numbers
“Job succeeded in # milliseconds”: put # where the number goes and set the limit. Works on emails, HTTP and TCP response times, and job duration. Each threshold is either an error or just a warning. Premium plan.
Schedules, windows and cron
Every N hours, daily, weekly or monthly. Start and cut-off time, chosen days, tolerance in minutes: whatever arrives late is “late”, not broken. On the Premium plan, a cron expression too, with a preview of the next runs.
HTTP and TCP services
GET, HEAD or POST with a body, expected status (200, 200|204, 2*), filters on body and headers, or simply a port that must open. With “Test now” before you save.
API checks
The job calls a URL when it finishes; if it never calls, it is MISSING. healthchecks.io-compatible: /start times the job, /fail and the exit code report a failure. Ready-made snippets, Duplicati included. Premium plan.
On-site probe
For what sits behind the firewall: a signed MSI installer on Windows, one line on Linux (systemd), a container on Synology, QNAP or Proxmox. It checks files, services, processes, ping and internal addresses; scripts can only be enabled on the machine, never from the portal. Offline, it keeps results with the right timestamps and delivers them as soon as it is back; updates are signed and arrive by themselves. Premium plan.
Groups, pause and hidden rows
Sort checks and services into a colour-coded group tree by dragging them. A pause, until a date or until you lift it, can cover a whole group: no MISSING, no alerts. And each user hides the rows they do not need.
31 OctThe report for your client.
Availability reportsPremium
A PDF to send to your customer: availability, minutes offline, the longest outage and every outage with start and end, per service, per group and overall. Generate it when you need it, or let it go out every week, month or quarter, with your logo. Premium plan.
Exports and history
30-day percentage per check and, for every day, what happened. CSV files are prepared on our servers: every single check run, only the outages, or a summary per day, hour or minute, ready for Excel or Power BI. Pick by group, service or single check. If a mailbox was disconnected for a while, “Recheck” re-reads the latest emails and fills the gaps.
Availability report
Acme Ltd · September 2026
Availability 99,98%
Offline 4 min
Unreachable twice, 4 min in total. Longest: 3 min, on 12/09 at 14:02.
outcomes-september.csvready · 40.8 MB
per-minute-summary.csv171,037 rows…
Security
We watch your email. We never touch it.
A monitor should be invisible to what it observes. The less data we keep, the less surface we expose. By principle, not by default.
Read-only IMAP
We never mark as read, never move, never delete. The mailbox stays exactly as it is: we only read it.
Credentials encrypted at rest
IMAP passwords, service credentials and your SMTP password are encrypted with AES-256-GCM. Never in clear text in the database, the logs or the API responses.
Multi-organisation isolation
Every query is filtered by organisation from the token, never from the request payload. One customer’s data never comes near another’s.
Two-factor authentication
TOTP with an authenticator app: optional for users, mandatory for the system administrator. No exceptions.
Revocable sessions
See where you are signed in and sign out other devices in one click. Every sign-in from a new address triggers an email, with a link that closes everything.
Targets kept in check
Private addresses and cloud metadata endpoints are blocked, redirects are not followed, and repeated sign-in attempts are throttled.
Pricing
Four tiers. One yearly fee.
Prices exclude VAT, billed yearly. You start free, with no expiry, and move to a tier when you need it.
A check is anything Mail Monitor verifies: an expected email, a service check or an API check. They all count together.
Free
To try it on one backup.
0€/monthforever
1 mailbox
2 email checks
1 service with 2 checks
1 user
Email notifications and one Telegram, Teams, Slack or webhook channel
More than 300 checks or 15 probes: tiers on request. [email protected]
Try Premium free for 30 days
Create the free account, then write to us to start the trial: for 30 days you get every Premium feature. At the end you pick a tier or stay on the free plan, without losing anything.
No price per check, per mailbox or per user.
Italian electronic invoicing.
Cancel at the yearly renewal.
Frequently asked
The short answers.
Can’t find your question?
Write to us: a person answers, usually the same day.
Mail Monitor is a SaaS that checks the things you expect and do not always get: recurring emails (backup reports, scheduled jobs, alerts, automated confirmations), services that must answer, and jobs that check in over an API. It tells you when something is missing.
How does it notice a missing email?
You define a check with an expected schedule (hourly, daily, weekly or monthly) and a cut-off time. If the window plus the tolerance expires and no email matching the rules has arrived, the check turns MISSING and the notification fires.
Is it only for backups?
No. Backups are the most common example, but it works for any recurring email (automated reports, cron results, antivirus alerts, e-invoicing confirmations) and for any service or job you need to know is alive.
What are service checks?
Checks we run ourselves, at a regular interval: an HTTP call with an expected status and filters on the response body, or opening a TCP port (RDP 3389, SQL 1433, SSH 22…). A service groups several addresses under one name: if they go down together you get a single alert, not one per address.
What about backups that send no email at all?
That is what API checks are for: your job calls a URL of ours when it finishes, and if the call does not arrive within the expected window the check turns MISSING. The URL is healthchecks.io-compatible, so borgmatic speaks it natively; for curl, PowerShell (Veeam, Scheduled Tasks), Duplicati and Proxmox Backup Server the snippet is ready in the interface.
How do I connect the mailbox?
Over IMAP, with the server address, a username and a password (or app password); the connection is verified before saving. Any provider that offers IMAP access with a password or app password will do. Our advice is a mailbox dedicated to backup reports. The mailbox is always opened read-only: we never mark as read, move or delete anything.
I use Microsoft 365: can I connect the mailbox?
Not directly. Exchange Online no longer accepts IMAP access with a password, not even with app passwords. You use a mailbox dedicated to backup reports, with a provider that offers IMAP with a password, and get the emails delivered there: from the backup software, by changing the recipient, or with an Exchange mail flow rule. Read the guide: Microsoft 365
Do I have to give you my company email password?
No, and we do not ask for it. You create a mailbox that only receives backup reports and give Mail Monitor the password for that one. People’s email stays out of it, and revoking access takes one password change. Read the guide: Microsoft 365
Is it compatible with healthchecks.io?
Yes, API checks use the same URL shape: a plain call when the job finishes, /start when it begins, /fail on failure and the exit code appended to the address, over HEAD, GET or POST. If you already use healthchecks.io you only change the domain, and tools that support it, borgmatic for one, work unchanged. The body of a POST call is evaluated with the same “must / must not contain” rules as emails.
Can I set thresholds on duration, response time or numbers written in an email?
Yes, on the Premium plan. Write the line as it appears, with # in place of the number (“Job succeeded in # milliseconds”), and set the limit. It works on email subject and body, on the body, headers and response time of HTTP checks, on TCP connect time, and on the duration of jobs that call /start. Each threshold is either an error, which fails the check, or a warning, which leaves the outcome as it is and shows up in the reason and, if you want, in an email.
Can I check servers and NAS boxes that are not reachable from the internet?
Yes, with the on-site probe (Premium plan). You install it on your network: a signed MSI on Windows, one command line on Linux, Docker on NAS boxes and servers; it connects with a token and opens no inbound port. From there it checks internal addresses, ping, backup files (presence, age, size), services, processes and, only if you enable them on the machine, scripts with an expected result. If it loses the connection it keeps working and delivers the results when it is back, with a single alert and a summary instead of a flood of MISSING.
How do I install the probe?
In the portal open Probes, give it a name and press “Create and install”: you get a ready line for Windows (a signed MSI, from an administrator prompt or an RMM), for Linux (one curl line with sudo, systemd service) and for Docker (a compose file to paste on the NAS). The token that links the probe to your account is already in the line and is shown only once. A few seconds later the probe shows as connected and you assign it checks. The full guide is under Guides, “On-site probe”.
The probe does not connect or shows offline: what do I check?
That the service is running (services.msc on Windows, systemctl status mmprobe on Linux, docker ps on Docker) and that the machine can reach the server over HTTPS on port 443: no inbound ports are needed. Errors are in probe.log, in the probe’s data folder. If the corporate antivirus blocked or deleted it (it happens with Kaspersky), add mmprobe.exe to the trusted applications and reinstall.
Can the probe run scripts? Is it safe?
Yes, but only if you decide so on the machine: scripts start disabled, and the mode is changed with a command on the probe, never from the portal. You can allow only scripts you put in a local folder, or also those written in the portal by admins. Probe updates are signed: it only installs packages carrying our signature.
How do I suspend a check during maintenance?
Pause it: until a date, after which it resumes on its own, or until you lift the pause. While paused, no checks run, nothing turns MISSING and no alerts go out. A pause applies to a check, a service or a whole group, and in that case everything inside the group inherits it.
Can I organise checks by customer or by site?
Yes, with groups: a tree as deep as you like, each group with its own name and colour, where you drag checks and services. Deleting a group does not delete what is in it. Each user can also hide the rows that do not concern them: they drop out of that user’s counts, but are still checked and still alert.
Can I alert my own customers?
Yes. Each organisation can configure its own SMTP server, logo and colours, so end-customer alerts go out in your name. There is a contact address book and reusable templates with placeholders (customer, check, state, date, reason…), with a live preview and a test send to any address. For each check you pick the recipients and the template for ERROR, MISSING and back-to-OK, plus a cooldown so the same alarm is not repeated endlessly.
Can I prove to a customer how long a service was really down?
Yes, with the PDF availability report (Premium plan). Pick the period and the items: for each service you get how many times it did not answer, for how many minutes in total, the longest outage and the list of every outage with start, end and duration; for emails and jobs, how many runs succeeded, failed or went missing. “Offline for 4 minutes last month”, in black and white. The report can go out on its own every week, month or quarter, to you and your customers, from your sender and with your logo.
Is my data safe?
IMAP passwords and service credentials are encrypted at rest with AES-256-GCM and never appear in clear text. Every organisation is isolated from the others, access can be protected with two-factor authentication, and sessions can be revoked at any time.
What kind of notifications does it send?
Instant alert per event, daily digest, or dashboard only. You can require N consecutive failures before anything fires: on a check that runs every minute, a reboot or a deploy should not wake anyone up.
Is there a free plan?
Yes, and it does not expire: one mailbox, two email checks, one service with two checks and one user. API checks and larger volumes are part of the Premium plan.
What does the Premium plan add?
No limits on mailboxes, checks, services and users, plus five reserved features: API checks, cron-expression scheduling, numeric thresholds, PDF availability reports with automatic delivery, and the weekly history archive. Everything else (rules, dashboard, groups, pause, notifications, customer alerts, CSV exports) is identical on both plans. The free limits only apply to what you create: nothing is lost when you move between plans.
How long is the history kept?
Outcomes of email and API checks are kept with no expiry. Outcomes of service checks, which may run as often as every minute, are kept for 95 days. Before they expire you can export them to CSV whenever you like. On the Premium plan it is taken care of: every week a ZIP archive is prepared, one CSV per day, and you get an email.
Try it on your own backups.
Connect a mailbox and define your first check in minutes. The free plan never expires: one mailbox, one service, and the backup you cannot see today, you will see tomorrow.